AI Data Extraction Services
AI that unlocks your data – extracting structured intelligence from unstructured documents to power your business.

AI data extraction is the use of artificial intelligence – OCR, natural language processing, computer vision, and large language models – to automatically identify, capture, and structure information from unstructured sources like PDFs, emails, contracts, and images. Instead of manual data entry, you get clean, decision-ready data flowing straight into your CRM, ERP, or BI tools.
Most organizations are sitting on a mountain of unstructured data. It lives in emails, PDFs, contracts, chat logs, call recordings, and scanned images – and without the right tools it stays locked away, hard to analyze, and underused. AI-powered data extraction changes that. By applying advanced AI and natural language processing, TRN Digital turns messy, unstructured content into structured information your teams and systems can actually act on.
The Challenge of Unstructured Data
Analysts estimate that nearly 80% of enterprise data is unstructured. That means the majority of your most valuable business information sits in formats traditional, rules-based tools were never built to process. Common sources include:
support conversations, internal communications
contracts, invoices, receipts, forms
with inconsistent, non-standard formatting
ID proofs, handwritten forms, design files
meeting recordings, call-center interactions, training sessions
reviews, blogs, and social posts
Handled manually, this volume is slow, error-prone, and expensive. Automated AI extraction removes the bottleneck - at a fraction of the cost and time.
What Is AI-Powered Data Extraction?
AI data extraction uses artificial intelligence, machine learning, and natural language processing to automatically identify, capture, and structure valuable information. Instead of a person reading through hundreds of documents, purpose-built AI models are trained to:
- Recognize entities such as names, dates, amounts, and line items
- Classify documents by type and route them automatically
- Summarize long text and surface the details that matter
- Interpret sentiment and intent in conversations and feedback
The output is structured, validated data that can flow directly into CRMs, ERPs, SharePoint, or BI dashboards for immediate action.
AI Data Extraction vs OCR vs IDP
These terms are often used interchangeably, but they solve different problems. OCR digitizes text. Intelligent document processing (IDP) is the end-to-end pipeline. AI data extraction is the intelligence at its core.
|
|
OCR
|
AI Data Extraction / IDP
|
|---|---|---|
|
What it does
|
Converts images of text into machine-readable characters
|
Reads, classifies, extracts, and validates structured fields with context
|
|
Understand context?
|
No - pure pattern matching
|
Yes - NLP and LLMs understand meaning and layout
|
|
Typical accuracy
|
~60–80% on variable layouts (typical)
|
~95–99% on structured/semi-structured documents, based on our delivery experience and the documented performance of Azure AI Document Intelligence.
|
|
Best for
|
Digitizing text for search or archiving
|
Operational workflows needing structured, validated data
|
|
Output
|
Raw text
|
Structured data routed to CRM / ERP / BI
|
In short: OCR gives you text; AI data extraction gives you accurate, structured, decision-ready data.
Our AI Data Extraction Services
TRN Digital designs, builds, and manages document-intelligence solutions end to end. Our services include:
- Document classification and data extraction across any document type
- Invoice and accounts-payable automation
- Contract and clause extraction and analysis
- Forms, KYC, and onboarding-document processing
- Custom AI model development for complex or industry-specific documents
- IDP pipeline design, integration, and deployment
- Accuracy evaluation, QA, and human-in-the-loop workflows
- Ongoing managed support and continuous model improvement
Built on Microsoft & Azure AI
As a Microsoft partner, TRN Digital builds AI data extraction on the technology your business already runs on. That means faster deployment, enterprise-grade security, and no bolt-on middleware. Our solutions leverage:
- Azure AI Document Intelligence (formerly Form Recognizer) for document parsing and field extraction
- Azure OpenAI for context, summarization, and complex reasoning over documents
- Power Automate for orchestration and straight-through processing
- Microsoft Syntex and SharePoint for content understanding and storage
Extracted data flows directly into SharePoint, Dynamics 365, Power BI, and your line-of-business systems – governed by your existing Microsoft 365 security and compliance controls.
Every engagement follows a proven, transparent pipeline:
Collect data from emails, documents, images, or media files
Apply OCR, computer vision, NLP, and machine learning
Identify key details like names, amounts, and dates
Organize extracted insights into databases or dashboards
Validate the output using independent LLMs and business rules
Models improve accuracy over time as they see more data
Accuracy, Evaluation & Human-in-the-Loop
In document extraction, being confidently wrong is the expensive failure – a missing value is visible, but a fabricated one can flow straight into a customer quote or a compliance record. TRN Digital engineers accuracy in layers so wrong data never reaches your systems:
- Confidence scoring on every extracted field
- Business-rule validation (totals that must reconcile, formats that must match)
- Independent LLM-based evaluation to cross-check results
- Human-in-the-loop review for low-confidence or high-risk fields
- Continuous learning that raises accuracy with every processed document
Key Benefits of AI Data Extraction
Automation and Efficiency
Cut repetitive manual work and reclaim hundreds of hours.
Accuracy and Consistency
Eliminate human errors and maintain high-quality data.
Scalability
Process millions of files, emails, or messages without adding headcount.
Compliance and Risk Reduction
Handle sensitive data securely, with full traceability.
Real-time Insights
Access critical information instantly instead of waiting on manual processing.
Security & Compliance
Your documents contain some of your most sensitive information, so security is built in, not bolted on. TRN Digital solutions run in secure, access-controlled Microsoft Azure environments and are designed to support the frameworks your industry requires:
- Encryption of data in transit and at rest
- Role-based access control and full audit trails
- Configurable data residency
- Support for HIPAA, SOC 2, and GDPR compliance requirements
Use Cases Across Industries
AI-driven data extraction delivers value anywhere high volumes of documents are processed by hand:
Finance
Automate loan reviews, extract invoice details, and streamline KYC
Healthcare
Process medical records, extract lab-report data, and analyze patient feedback
Legal
Review contracts, identify clauses, and manage case documents
Insurance
Accelerate claims intake and adjudication
Retail and E-commerce
Categorize feedback, analyze receipts, and study buying patterns
IT and Managed Services
Automate support-ticket categorization, log analysis, and compliance reporting
Integrations
Extracted data is only useful where your teams already work. TRN Digital integrates extraction output with Microsoft 365, SharePoint, Dynamics 365, Power BI, and your existing CRMs and ERPs – so structured data lands in the right system automatically.
Traditional vs AI Data Extraction

- Manual and time-consuming
- Prone to human error
- Limited scalability
- Costly and inefficient
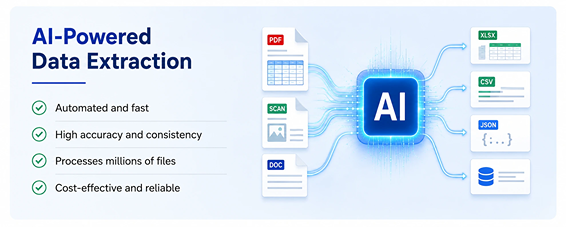
- Automated and fast
- High accuracy and consistency
- Processes millions of files
- Cost-effective and reliable
Implementation Approach & Timeline
We de-risk adoption by proving value before scaling. A focused pilot on a single, high-volume document type typically goes live in 4–8 weeks. Once accuracy and ROI are validated, we phase the rollout across additional document types and departments – with governance, evaluation, and support built in at every stage.
ROI & the Cost of AI Data Extraction
Manual document processing typically costs an estimated $6–$15 per document once labor, error correction, and rework are counted. AI-powered extraction commonly reduces this to roughly $3–$5 per document. (Figures are typical industry estimates / TRN analysis, not definitive.)
Why Choose TRN Digital
TRN Digital combines deep Microsoft expertise with advanced AI to deliver document intelligence that integrates cleanly with your existing systems and produces measurable outcomes.
- Microsoft partner with Azure and Copilot credentials
- Secure, scalable, compliance-ready solutions (SOC 2 aligned)
- Custom AI models tailored to your documents and workflows
- Native integration with Microsoft 365, Power Platform, CRMs, and BI dashboards
- Proven delivery for enterprise clients across regulated industries
Related Blogs


Frequently Asked Questions
AI data extraction is the use of artificial intelligence - combining OCR, natural language processing, computer vision, and large language models - to automatically identify, capture, and structure information from unstructured sources such as PDFs, emails, contracts, and images. Unlike manual entry or basic OCR, it understands context, so the output is clean, structured data ready for your CRM, ERP, or BI tools.
OCR only converts images of text into machine-readable characters; it does not understand meaning. AI data extraction uses OCR as one step, then adds document classification, contextual understanding, field-level extraction, and validation. In short: OCR gives you text, while AI data extraction gives you accurate, structured, decision-ready data - typically at far higher accuracy on variable documents.
Intelligent document processing (IDP) is the end-to-end automation of reading documents through five stages: ingest, classify, extract, validate, and integrate. It combines OCR, AI/ML, NLP, and large language models to turn any document type into structured data routed to your systems. AI data extraction is the core extraction step within an IDP pipeline.
Modern AI data extraction and IDP platforms commonly reach 95–99% field-level accuracy on structured and semi-structured documents, versus roughly 60–80% for traditional OCR on variable layouts. Accuracy depends on document quality and complexity. Human-in-the-loop review and automated LLM-based evaluation raise production accuracy further and catch the errors that matter most.
AI can extract data from virtually any unstructured source: PDFs, scanned images, invoices, receipts, contracts, forms, emails, chat logs, spreadsheets, handwritten notes, ID documents, and audio or video transcripts. It handles structured, semi-structured, and unstructured formats, across multiple languages and mixed layouts.
Manual document processing typically costs an estimated $6–$15 per document once labor, error correction, and rework are counted. AI-powered extraction commonly reduces this to roughly $3–$5 per document. (Figures are typical industry estimates / TRN analysis, not definitive.)
Yes - when built correctly. Enterprise-grade solutions run in secure, access-controlled environments such as Microsoft Azure, encrypt data in transit and at rest, maintain full audit trails, and support compliance frameworks including HIPAA, SOC 2, and GDPR. Data residency controls, role-based access, and human-in-the-loop review keep sensitive information safe and traceable.
TRN Digital builds AI data extraction on the Microsoft stack - Azure AI Document Intelligence, Azure OpenAI, Power Automate, and Microsoft Syntex - so extracted data flows directly into SharePoint, Dynamics 365, Power BI, and your line-of-business systems. This native integration means faster deployment, enterprise-grade security, and no bolt-on middleware.
Yes. Modern AI extraction combines OCR with computer vision and language models to read handwritten notes, scanned forms, and low-quality images, then validate the results. Accuracy is lower on messy handwriting than on typed text, so human-in-the-loop review is applied to high-stakes fields.
Many common document types - invoices, receipts, IDs - work with pre-trained models out of the box. For unique or complex documents, a small labeled sample is used to tune a custom model. TRN Digital blends pre-trained models, custom extraction, and continuous learning so accuracy improves over time.
TRN Digital uses a multi-layer approach: confidence scoring on every field, business-rule validation, independent LLM-based evaluation, and human-in-the-loop review for low-confidence or high-risk fields. Because a fabricated value is costlier than a flagged one, the pipeline surfaces uncertainty rather than guessing - so wrong data never reaches your systems.
Unlock the Value of Your Data Today
Unstructured data is only a challenge while it stays hidden. With AI-powered extraction from TRN Digital, you can turn emails, documents, and multimedia into business-ready insights that fuel growth – securely, accurately, and at scale.